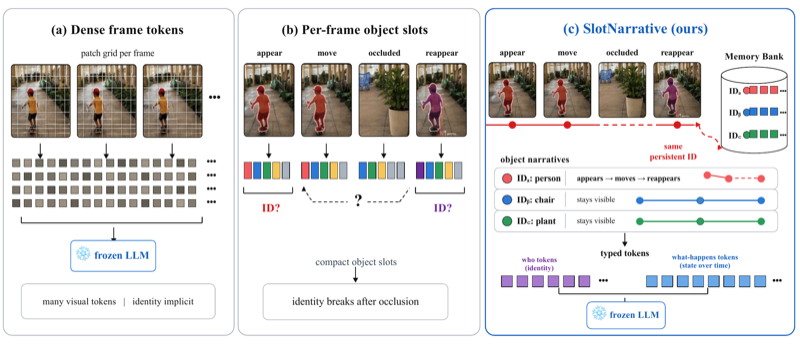
Persistent Object Narratives for Token-Efficient Video Language Models
arXiv preprint, 2026
Compact identity and state tokens connect recurring objects across time, providing a token-efficient interface for Video-LLMs.
Overview & resourcesI am a Ph.D. student in Computer Science at Tianjin University, advised by Xiaojie Guo (郭晓杰). Previously, I received my M.S. in Computer Science from Johns Hopkins University (January 2024–May 2025) and my B.Eng. in Software Engineering from Beijing Jiaotong University (2019–2023).
My research focuses on computer vision, video understanding, and vision-language models. I am particularly interested in how models preserve object identity and state over time, reason from visual evidence, and represent videos efficiently. My earlier work includes tiny-object detection and mixed-precision quantization.
I welcome discussions about research and potential collaborations. Please feel free to contact me.
arXiv preprint, 2026
Compact identity and state tokens connect recurring objects across time, providing a token-efficient interface for Video-LLMs.
Overview & resources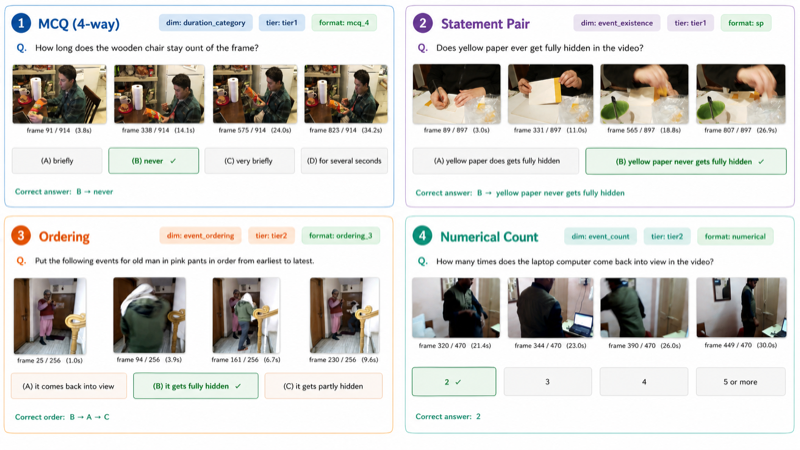
arXiv preprint, 2026
A diagnostic benchmark for object identity, state, and temporal continuity, grounded in object tracks and ordered visual evidence.
Overview & resourcesPh.D. student in Computer Science
M.S. in Computer Science
B.Eng. in Software Engineering